Automate a well-understood handoff first. Keep exceptions visible and give every failed run an owner.
Look for waiting, not just repetitive clicking
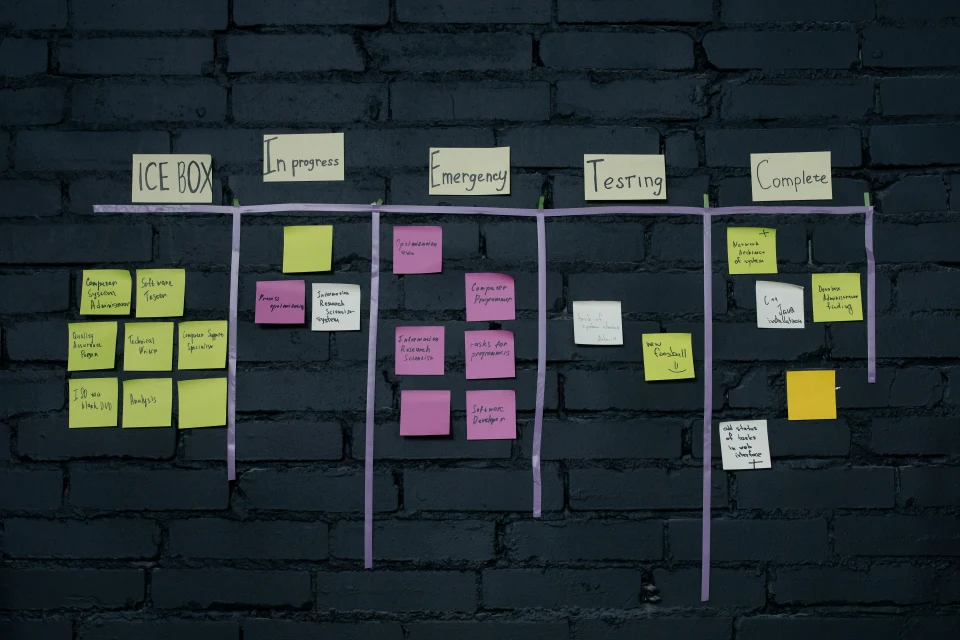
A workflow may contain only a few minutes of manual work but spend days waiting between teams. Map the path from the first request to completion. Record who acts, what information they need, and where work stops. The largest opportunity may be a missing notification or an unclear owner.
Take an incoming service request as an example. Someone copies it from email, checks the account, asks for missing details, and assigns it to a team. Before automating, agree on the required fields and what makes a request ready. Automating an ambiguous process only moves the ambiguity faster.
- Receive request
- Check required details
- Route or request review
- Track completion
Separate rules from judgment
Deterministic rules work well when the inputs and decisions are explicit. Route a request by a known account identifier, validate required fields, or create a task after approval. Keep these steps predictable and explainable.
AI may help interpret free text or prepare a summary, but the resulting suggestion is not the same as a verified fact. For an ambiguous enquiry, show the source text and proposed classification to a reviewer. Design the workflow so the reviewer can correct it without starting over.
Swipe the table to compare all columns →
| Step | Approach | Exception path |
|---|---|---|
| Required field check | Explicit validation rule | Request missing information |
| Account lookup | Verified system identifier | Send unmatched records to review |
| Free-text interpretation | AI-assisted suggestion if useful | Show source and allow correction |
| External system update | Tracked API operation | Retry safely or assign an owner |
Make retries safe and failures understandable
An integration can time out after the receiving system has already completed the action. Retrying blindly can create duplicate tasks or notifications. Use a stable operation identifier where the receiving system supports it, and design duplicate handling as part of the integration contract.
Record the state of each run, the last successful step, and what needs attention. A failed run should not disappear into a log that only a developer can interpret. Give operations staff a clear distinction between waiting, retrying, and requiring manual intervention.
Pilot one workflow before expanding
Run a small pilot with representative inputs, including incomplete and unusual requests. Compare elapsed completion time, correction effort, and the number of handoffs before and after the change. Do not count every automated action as time saved if somebody still has to verify or repair it.
Keep a manual route available while the new process is being evaluated. Expand when the team can explain what the automation does, how it fails, and how to recover. The best result is less chasing and clearer ownership, not simply a longer chain of connected tools.